Why small language models matter for enterprise AI
Small language models are gaining attention because enterprises increasingly need to match model capability to the work, data boundary, latency target, and operating budget. A smaller model may be suitable for a narrow classification, extraction, routing, or drafting task, while a larger model can remain available for ambiguous requests that need broader reasoning. The useful trend is not simply “smaller is better”; it is choice across a model portfolio.
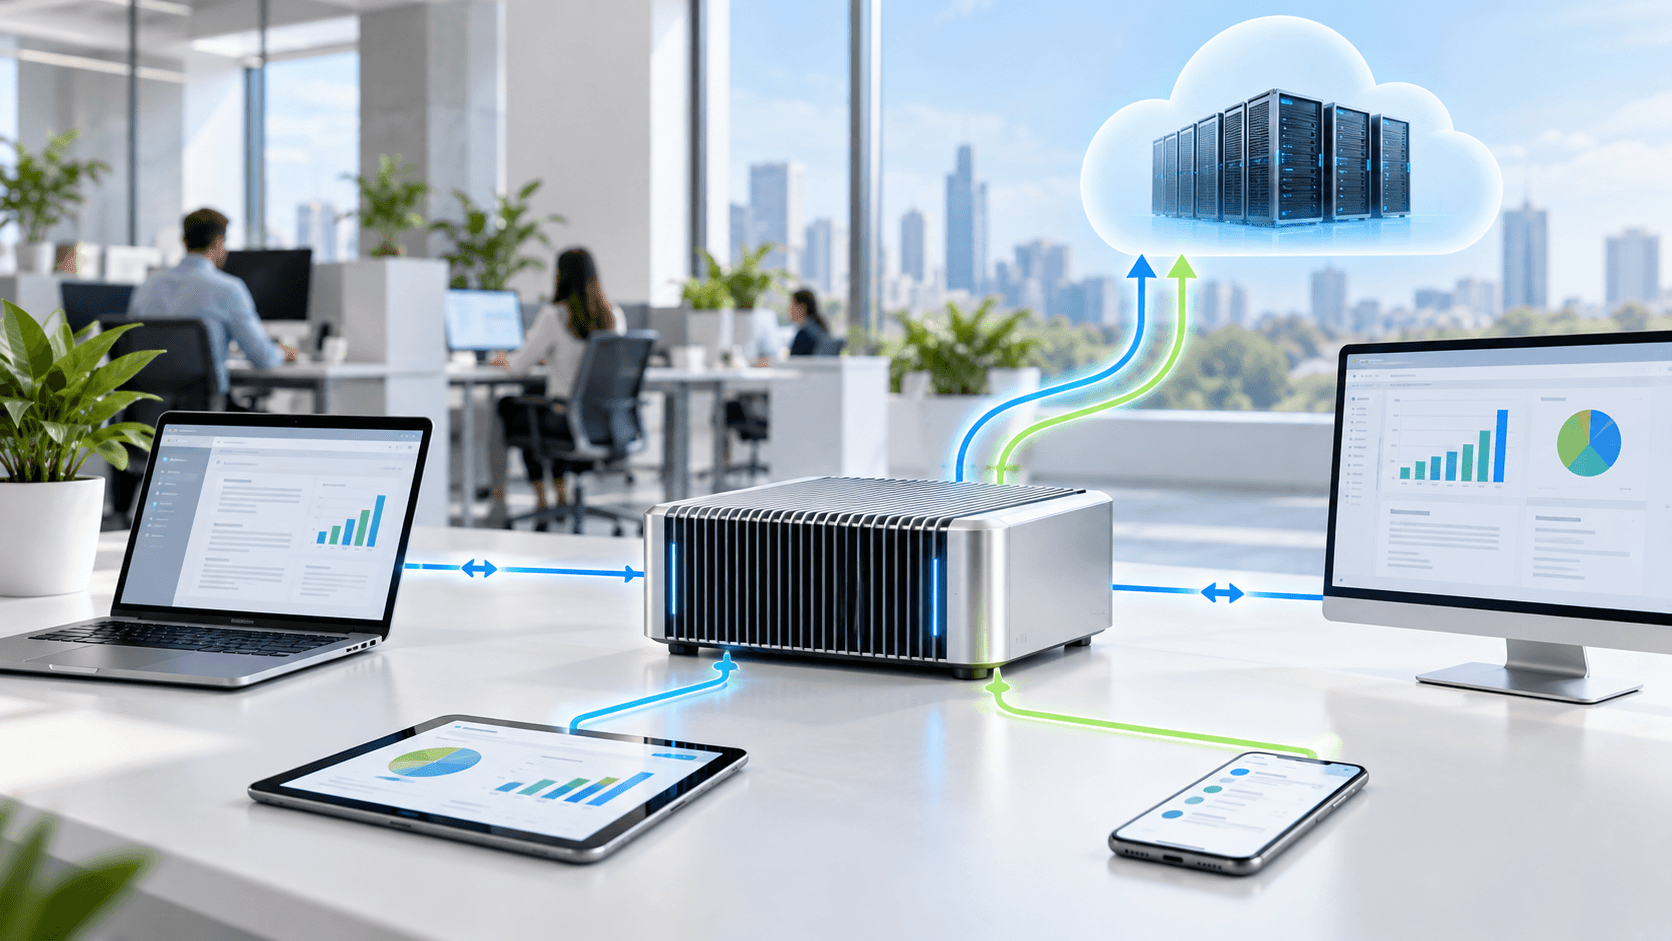
SLMs can also make some deployment options more practical, including private cloud, on-premise infrastructure, or edge environments. These choices may help with response time, data residency, or connectivity constraints, but they do not automatically remove security or operating responsibilities. Teams still need model evaluation, access control, patching, monitoring, and a plan for behavior that falls outside the model’s strengths.
The business case should compare capability with the cost of operating the complete service. Hardware utilization, peak throughput, upgrades, specialist support, and idle capacity can outweigh a lower inference price. For hosted models, include provider terms, network transfer, and service commitments. Use the same workload and quality criteria for every deployment option.
Choose tasks that fit a smaller model
Good candidates have a clear input and output, recurring patterns, bounded context, and a quality measure that domain experts can define. Examples may include routing a request to a queue, extracting known fields from a form, classifying an internal document, or drafting a response from an approved knowledge set. A small model is easier to justify when the workflow already has rules and examples that clarify success.
Avoid selecting a model based on parameter count or an impressive benchmark alone. Test it on your own permissioned data, including rare formats, ambiguous cases, language variation, and adversarial inputs. Measure exact task success, unsupported answers, human correction, latency, and cost. Keep a deterministic route or human review when confidence is low or the impact of an error is high.
Check performance by subgroup and input condition where those distinctions matter. A model may perform well on common English requests but struggle with regional language, scanned documents, or specialized abbreviations. Have representative users review outputs and failure messages. A narrow model is a good fit only when its boundaries are understood by the people who rely on it.
Use routing to combine SLMs, LLMs, and software
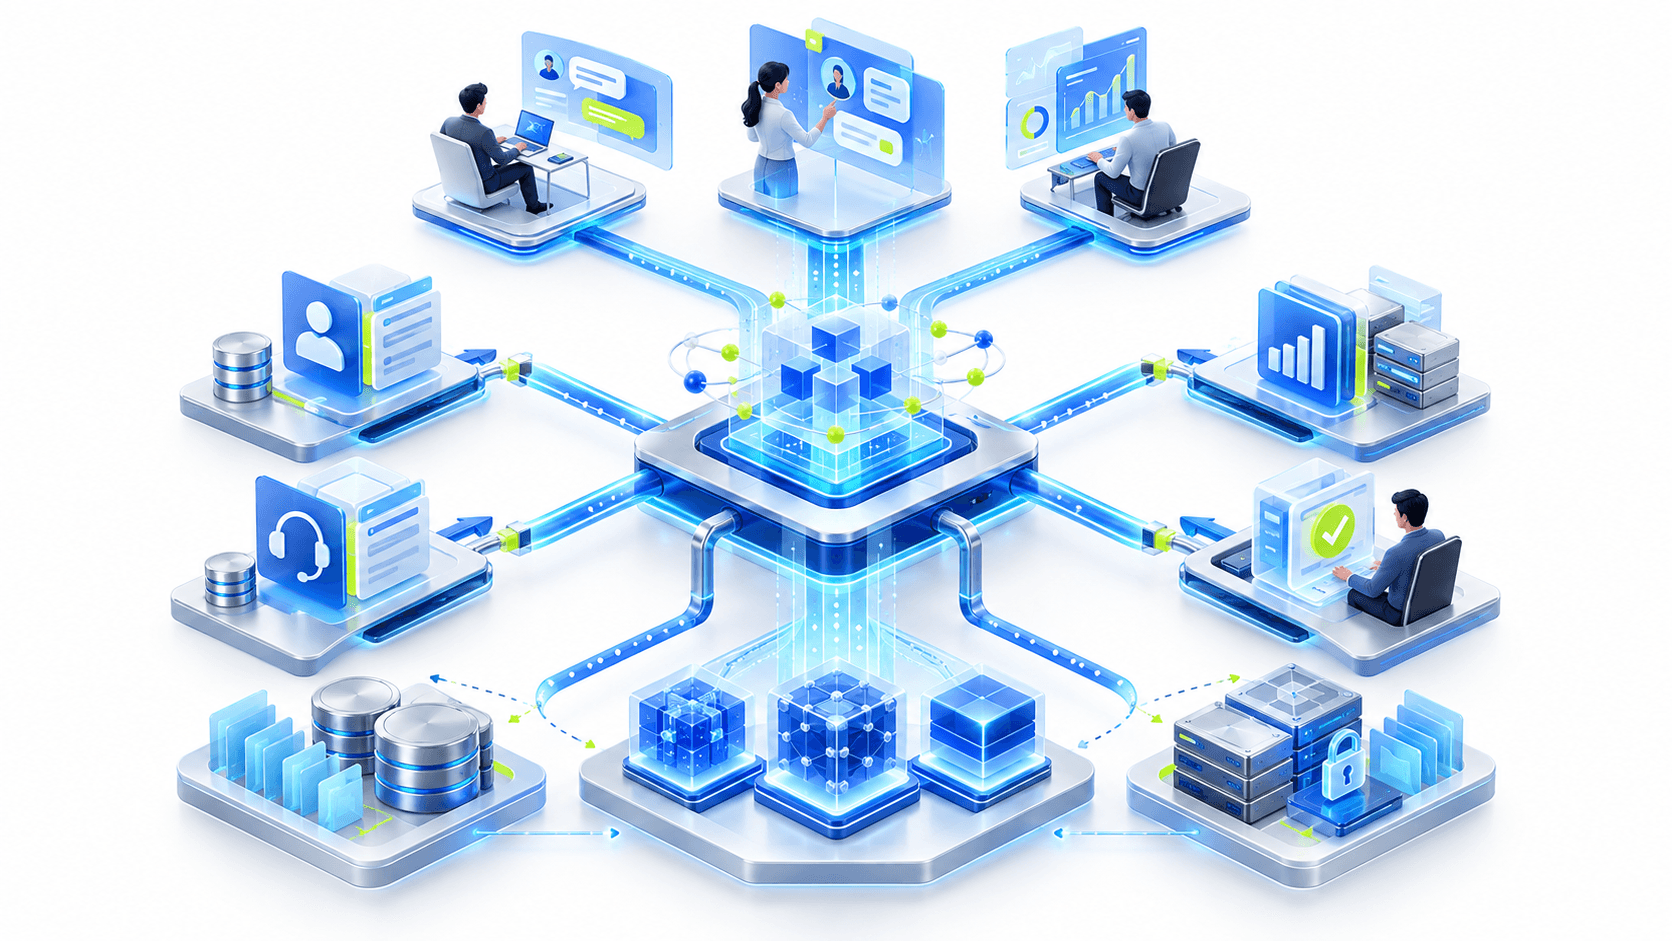
A hybrid AI architecture can direct stable rules to conventional code, common bounded tasks to an SLM, and complex or uncertain requests to a larger model or a person. The routing decision can consider task category, data sensitivity, confidence, service level, and cost ceiling. Make the path visible in logs and ensure the fallback does not expose data to a provider that is not approved for that information.
Evaluate the whole routed workflow, not each model in isolation. Test whether classification sends examples to the right path, whether escalation works, and whether retries or fallback increase latency or cost unexpectedly. Track the accepted outcome and the work needed to reach it. If routing adds complexity without meaningful gains in quality, privacy, availability, or economics, a single model may be the better design.
Keep the router simple enough to validate. Prefer explicit rules for known task categories and a measured confidence or review path for uncertain ones. Avoid circular fallback behavior in which models repeatedly reconsider the same request. Set limits for context, calls, and execution time, and make the final route visible to operators diagnosing an unexpected result.
Compare deployment and adaptation options
A hosted small model can reduce infrastructure work while still offering a smaller capability tier. A self-hosted model may provide more control over runtime and data location, but requires teams to operate compute, capacity, upgrades, security, and reliability. Fine-tuning or adapters can improve fit for a stable domain task, while retrieval can provide current facts without embedding every document into model parameters.
Choose the least complex method that meets the requirement. Begin with prompt design and retrieval when knowledge changes frequently. Consider adaptation when repeated evaluation shows a stable behavior gap that examples or workflow changes cannot solve. For private deployment, estimate hardware utilization and operations effort under real demand rather than comparing only a provider’s per-call price with a server purchase.
Data preparation can matter more than the adaptation method. Remove duplicates, resolve conflicting labels, protect personal information, and reserve separate examples for evaluation. Keep a record of data provenance and intended use. If a task depends on current policy or inventory, retrieve from an authoritative source instead of embedding facts that may soon become stale.
Build an adoption plan that protects quality
Start with one workflow owner, a representative evaluation set, and a baseline for current quality, cycle time, cost, and human effort. Run the SLM in an offline evaluation or shadow mode before it influences live work. Review errors with domain experts and include security, privacy, and infrastructure teams early if the deployment changes where data or inference runs.
Release to a small cohort with monitoring, feedback, escalation, and rollback paths. Watch for changes in data, vocabulary, request mix, or upstream software that can degrade performance. Reassess the model and its cost as usage evolves. Maintain model and prompt versions, evaluation results, and clear ownership so teams can reproduce a decision or safely switch providers.
Plan capacity around realistic concurrency and peak periods, not only average request volume. Confirm how the service behaves when local hardware is unavailable, an update must be rolled back, or demand exceeds throughput. A hybrid fallback can improve continuity, but only if its data destination is authorized and its cost and service limits are understood before an incident.
Explore: FIX technology stack
What CTOs should consider for SLMs in 2027
Treat small language models as one part of an AI portfolio, not a blanket replacement for larger systems. Compare SLMs and LLMs on the same representative tasks, using task quality, total operating cost, data controls, service reliability, and maintenance burden. Account for evaluation, orchestration, hardware, support, and human review as well as inference. Select based on the workflow’s constraints and business outcome.
FIX Intelligence, part of FIX Solutions JSC, helps organizations assess AI use cases, data and deployment needs, and model integration options. A focused proof of value can identify whether an SLM, a hosted model, a routed combination, or standard automation is the right fit. The strongest 2027 strategy will keep model choice flexible while keeping quality, permissions, and accountability explicit.